One more time, for the people in the back: If you are rejecting a null hypothesis based on a p-value that is just below 0.05, you are rejecting it based on evidence that is worth no more than a bare mention (Sellke et al., 2001; Jeffreys, 1939). Worse still, the evidence may actually support the null hypothesis rather than undercut it. Here are Berger & Delampady (1987) going for the jugular:
First and foremost, when testing precise hypotheses, formal use of P-values should be abandoned. Almost anything will give a better indication of the evidence provided by the data against H0 (p. 330; italics added for emphasis).
On this blog, I have tried to clarify this in an ongoing series of post:
- Redefine Statistical Significance Part I: Sleep Trolls & Red Herrings
- Redefine Statistical Significance Part II: Caught in a Bad Romance?
- Redefine Statistical Significance Part III: Informed Priors and Oracle Priors
- Redefine Statistical Significance Part IV: A Second Demonstration
- Redefine Statistical Significance Part V: A Wizard Walks Into a Sauna and Starts Pawing at a Pizza…
- Redefine Statistical Significance Part VI: Another Nail in the .05 Coffin
- Redefine Statistical Significance Part VII: Bursting the Bubble
- Redefine Statistical Significance Part VIII: How 88 Authors Overlooked a Giraffe and Sailed Straight into an Iceberg
- Redefine Statistical Significance Part IX: Gelman and Robert Join the Fray, But Are Quickly Chased by Two Kangaroos
- Redefine Statistical Significance Part X: Why the Point-Null Will Never Die
- Redefine Statistical Significance Part XI: Dr. Crane Forcefully Presents…a Red Herring?
- Redefine Statistical Significance Part XII: A BITSS debate with Simine Vazire and Daniel Lakens
- Redefine Statistical Significance XIII: The Case of Ego Depletion
- Redefine Statistical Significance XIV: “Significant” does not Necessarily Mean “Interesting”
- Redefine Statistical Significance Part XV: Do 72+88=160 Researchers Agree on P?
- Redefine Statistical Significance Part XVI: The Commentary by JP de Ruiter
- Redefine Statistical Significance XVII: William Rozeboom Destroys the “Justify Your Own Alpha” Argument…Back in 1960
- Redefine Statistical Significance XVIII: A Shockingly Honest Counterargument
- Redefine Statistical Significance XIX: Monkey Business
- Redefine Statistical Significance XX: A Chat on P-values with ChatGPT
- Redefine Statistical Significance Part XXI: Edgeworth Proposed the .005 Criterion Back in 1885
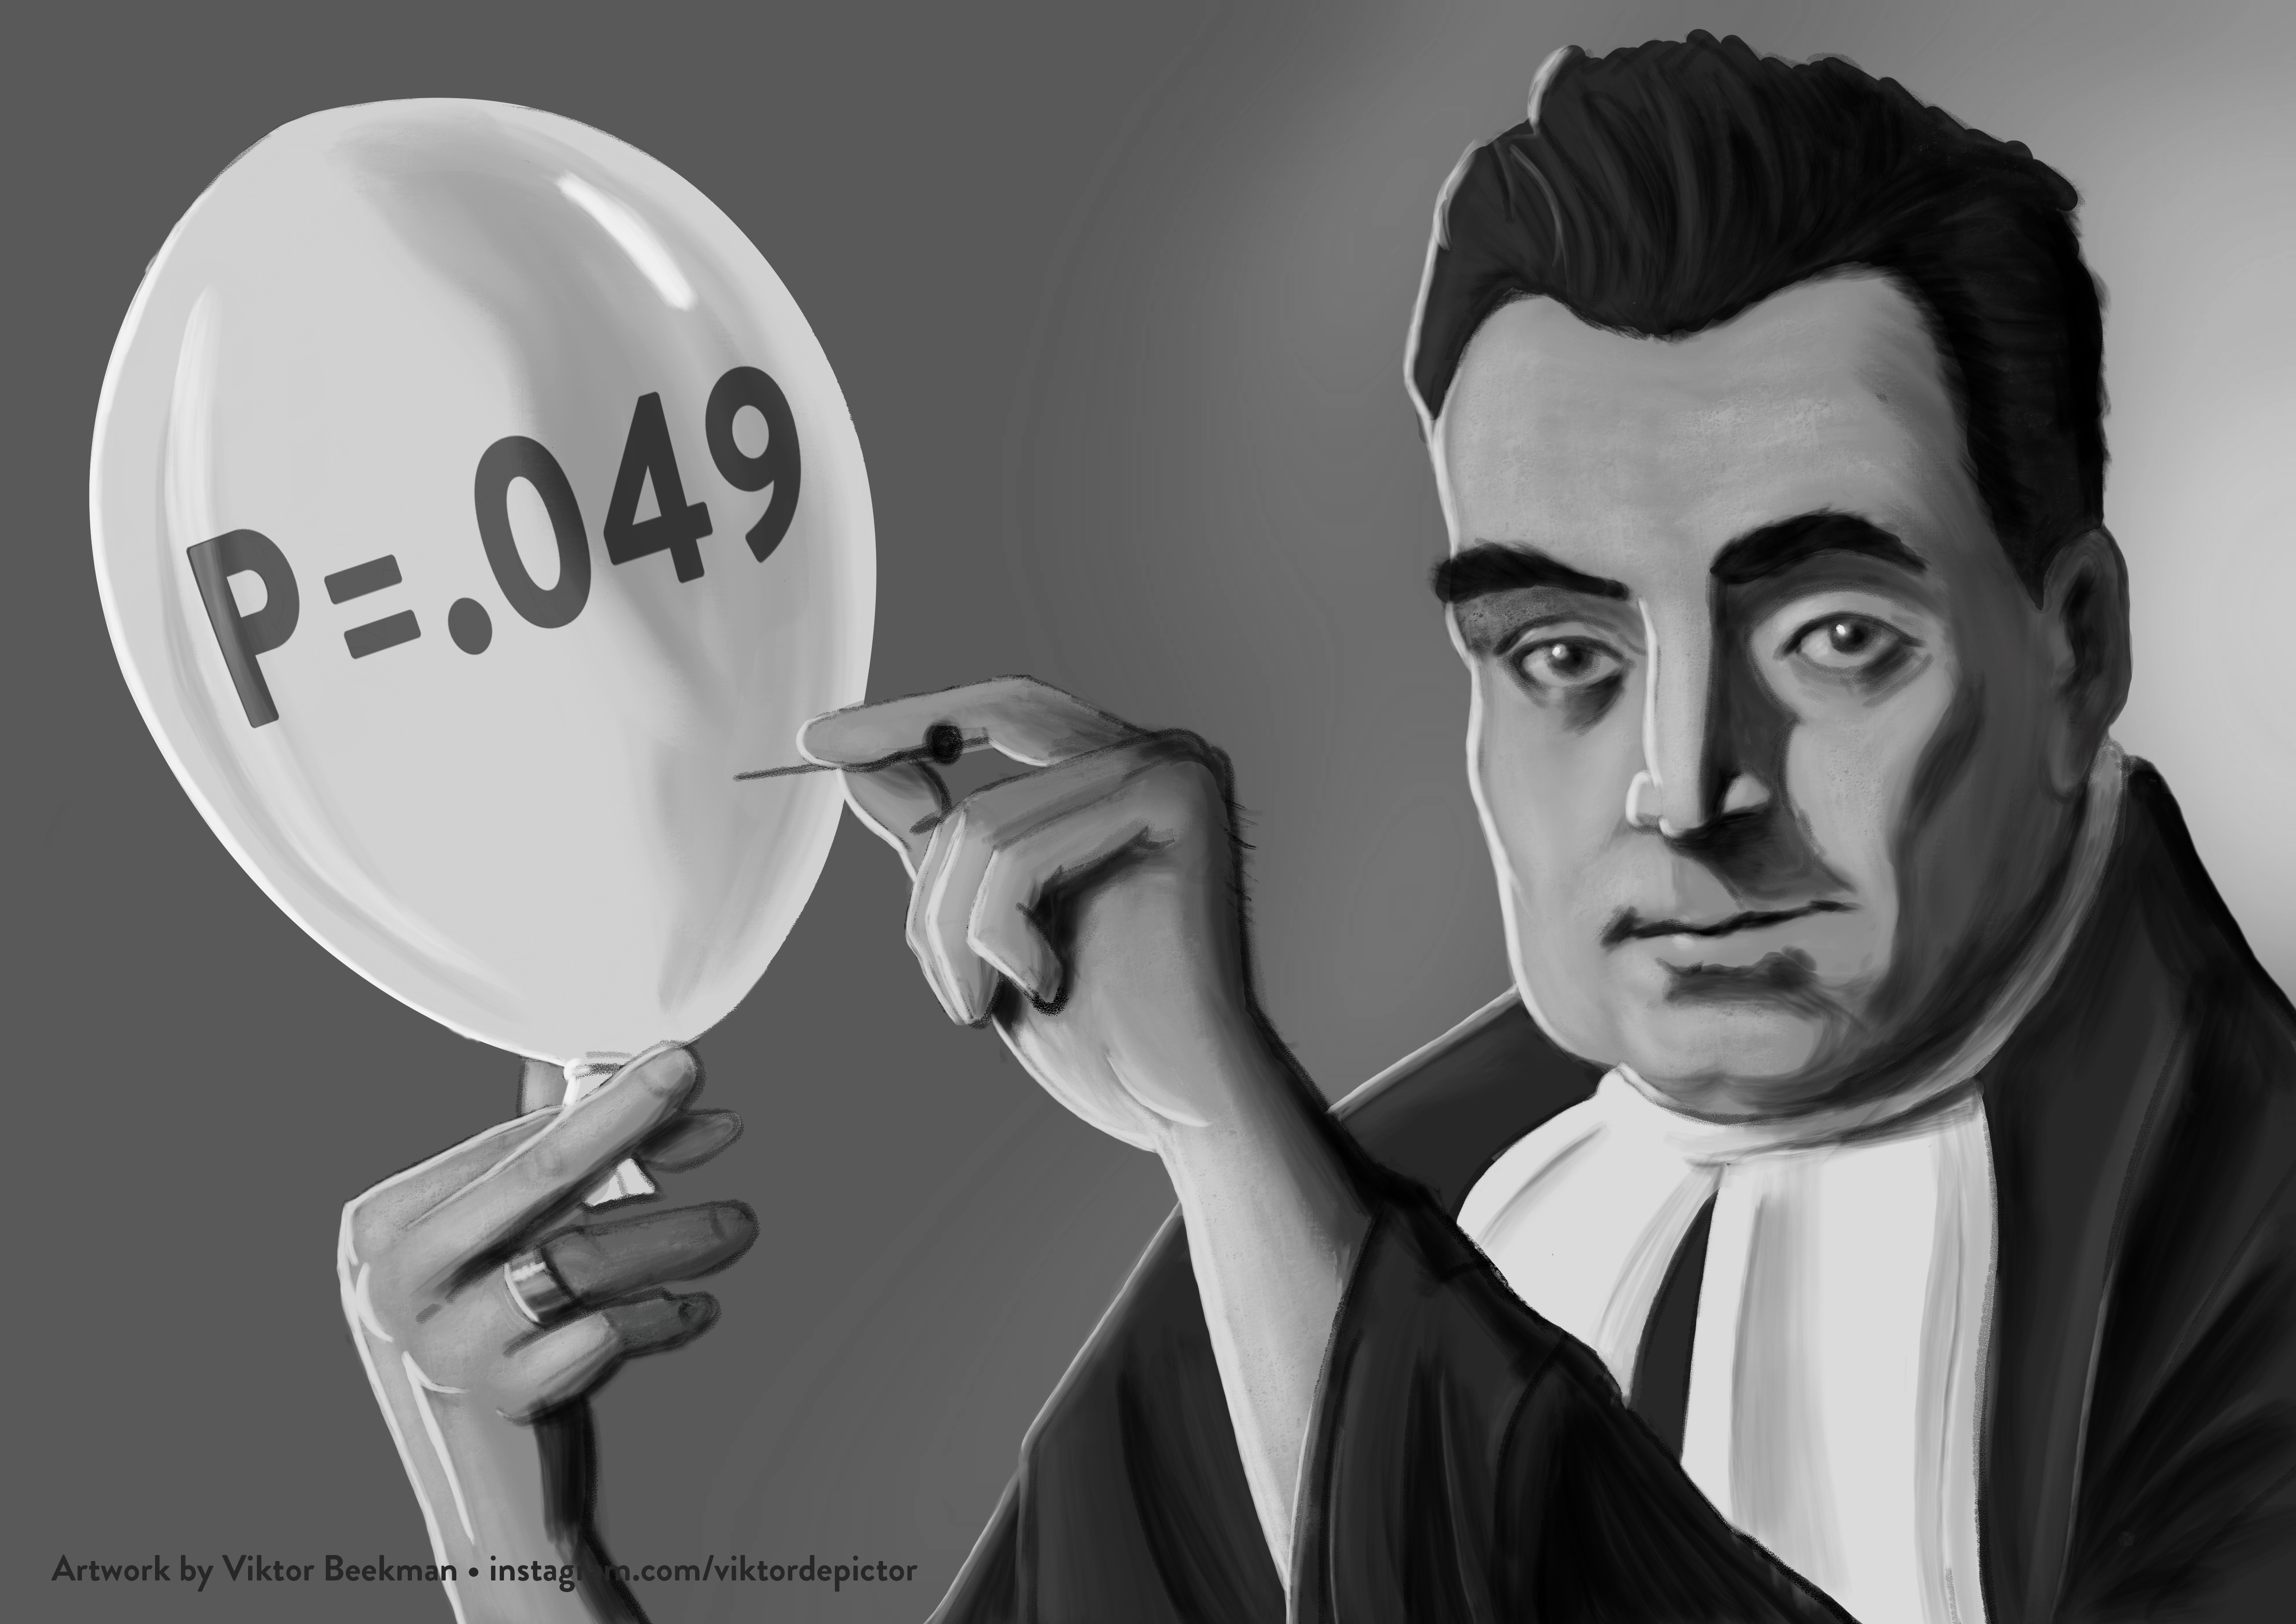
The entire debate is perhaps best captured by the following moving gif (based on a CC-BY drawing from Viktor Beekman):
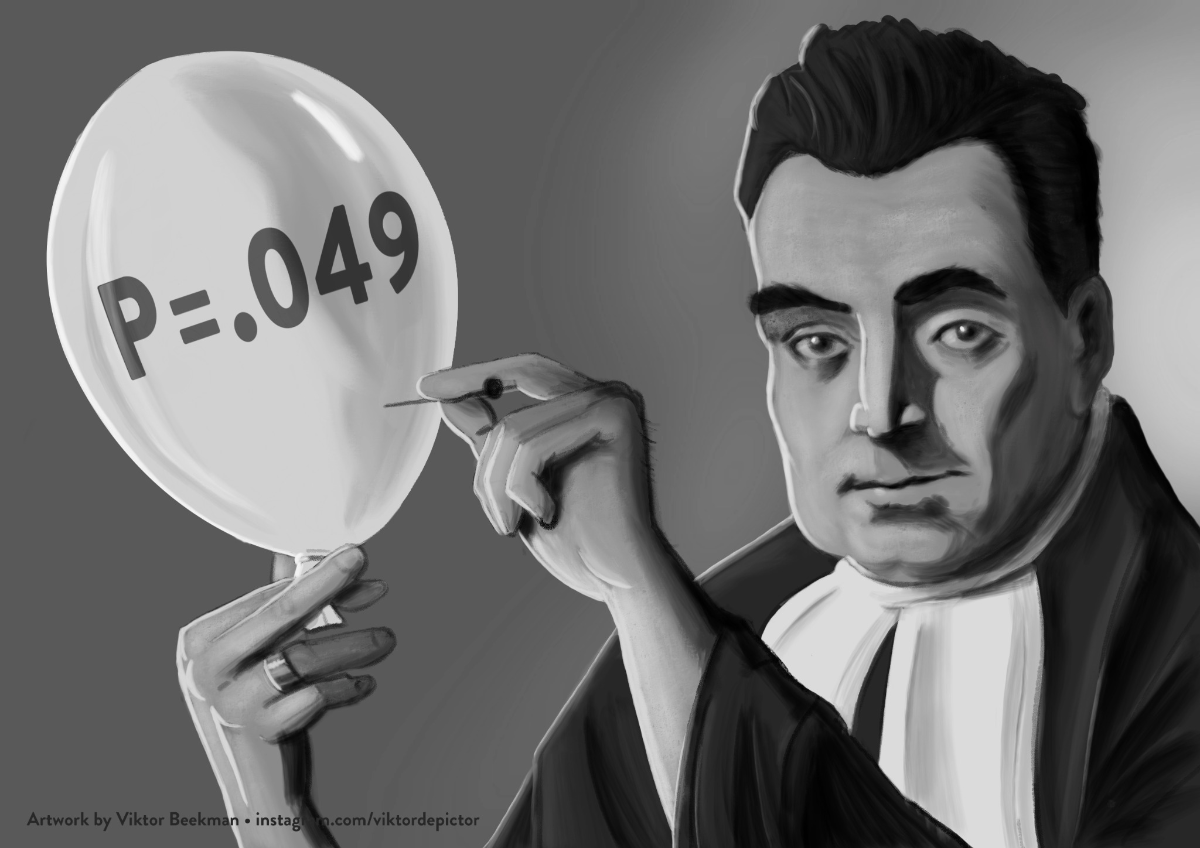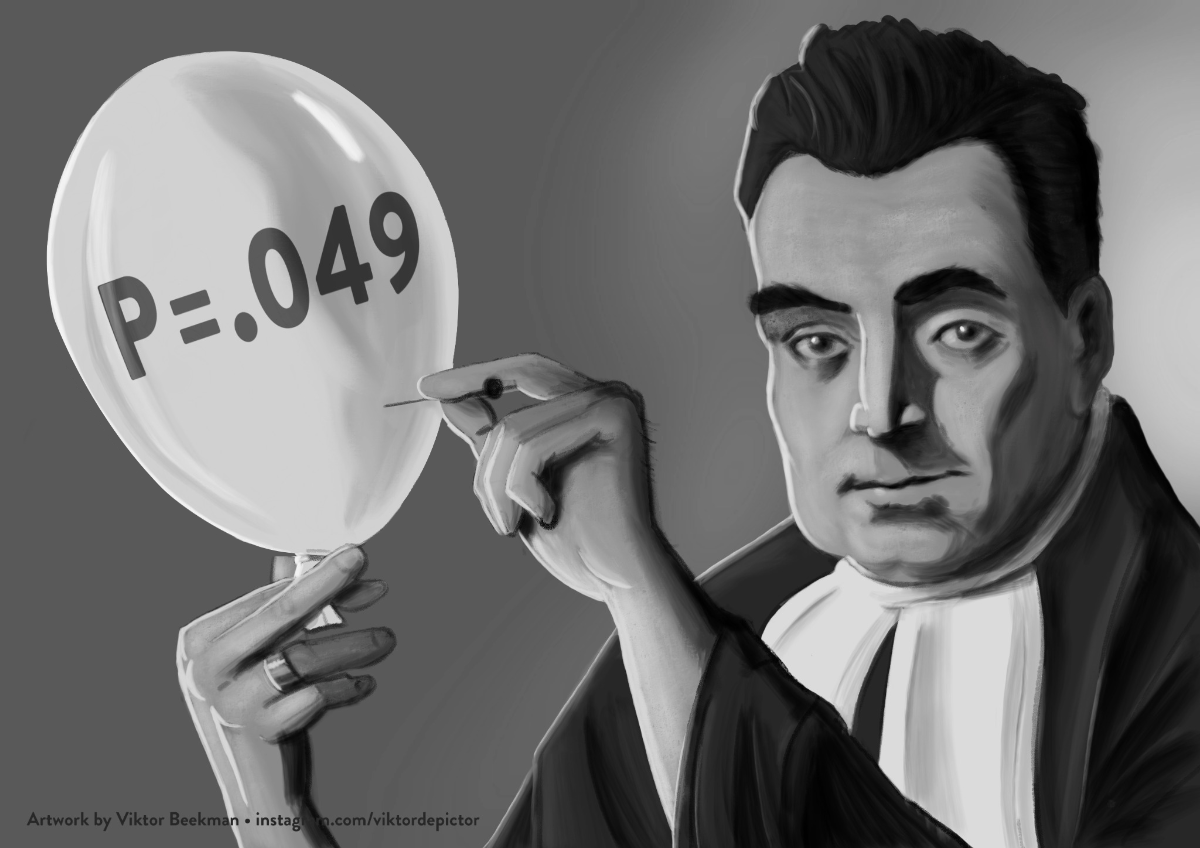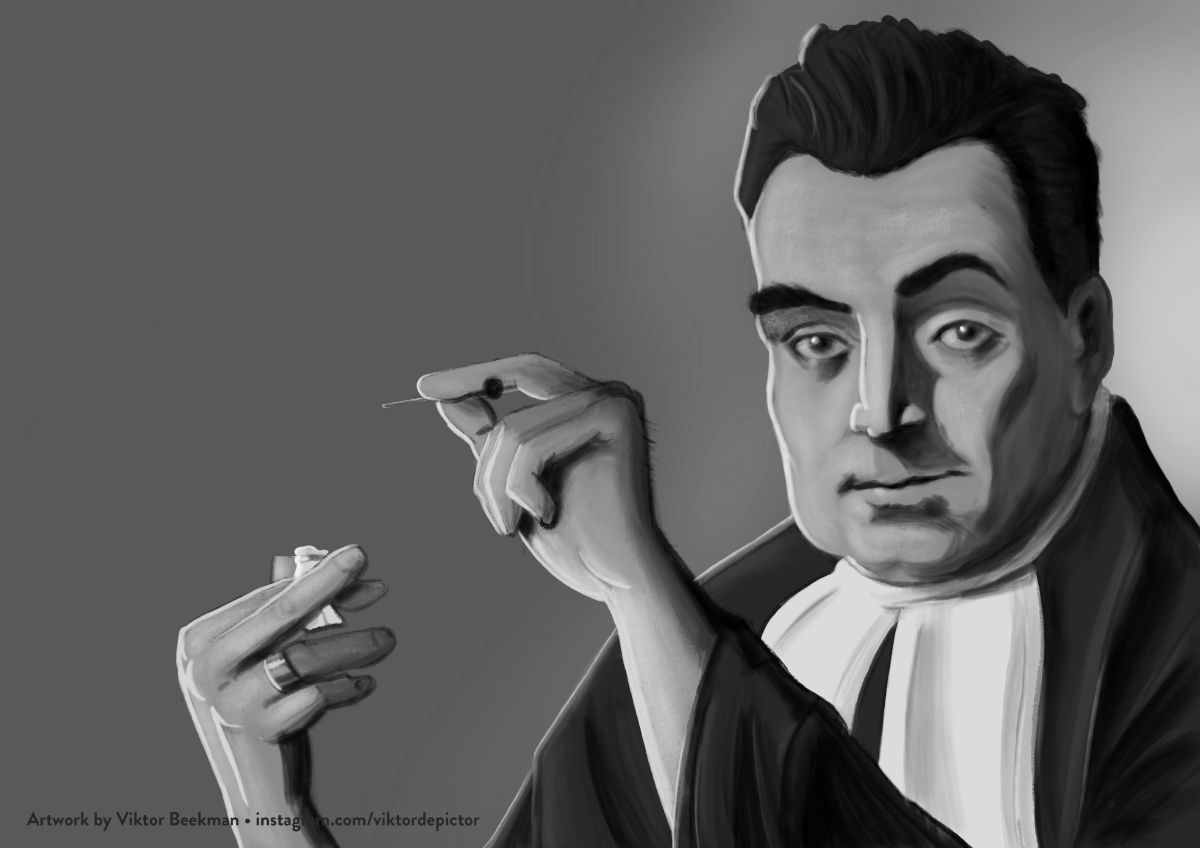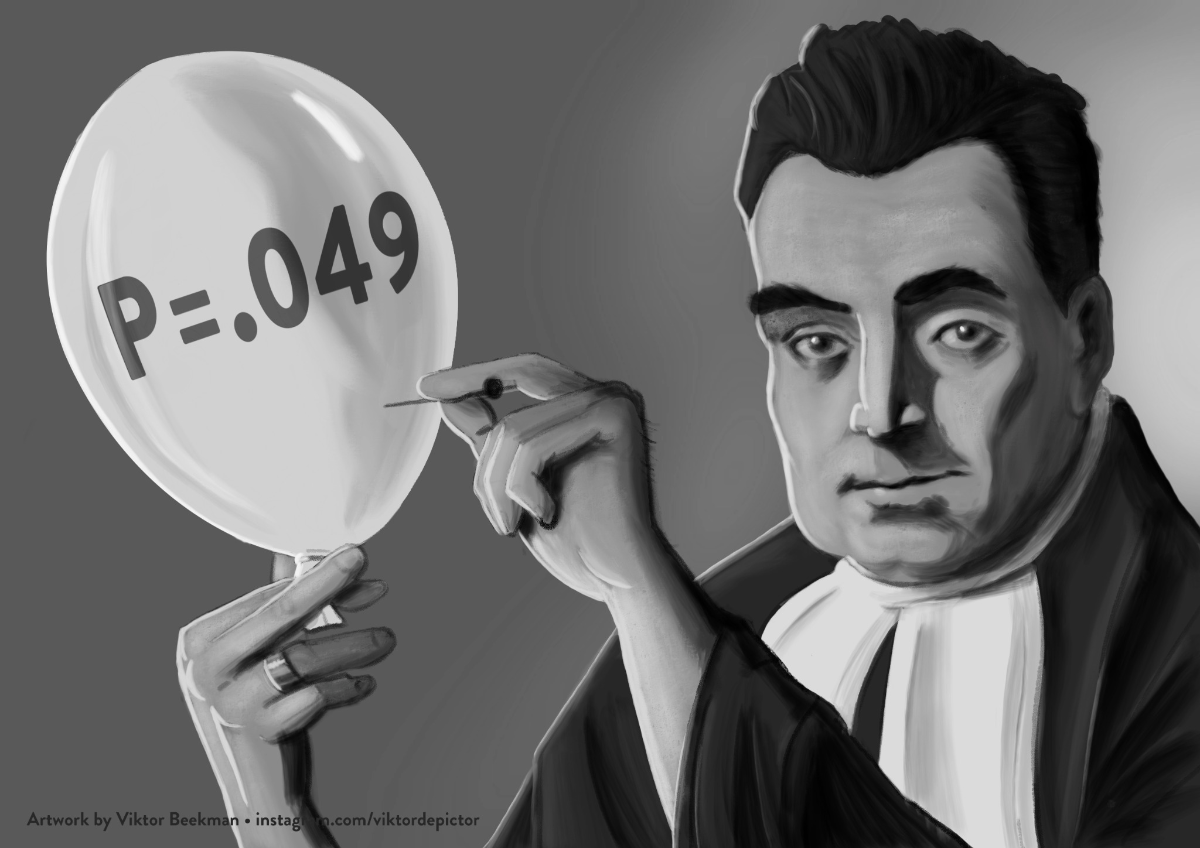
References
Berger, J. O., & Delampady, M. (1987). Testing precise hypotheses. Statistical Science, 2, 317-352.
Jeffreys, H. (1939). Theory of Probability. Oxford: Oxford University Press.
Sellke, T., Bayarri, M. J., & Berger, J. O. (2001). Calibration of p values for testing precise null hypotheses. The American Statistician, 55, 62-71.
Eric-Jan Wagenmakers
Eric-Jan (EJ) Wagenmakers is professor at the Psychological Methods Group at the University of Amsterdam.
Moving gif created by ChatGPT Pro based on the drawing by Viktor Beekman, available under a CC-BY license on this website.